≈ $1,396
API-equivalent value, 30 days. Three tiers, labelled by how each is known: $126 logged action by action, $1,124 of repeat reads avoided, $146 of other estimates.
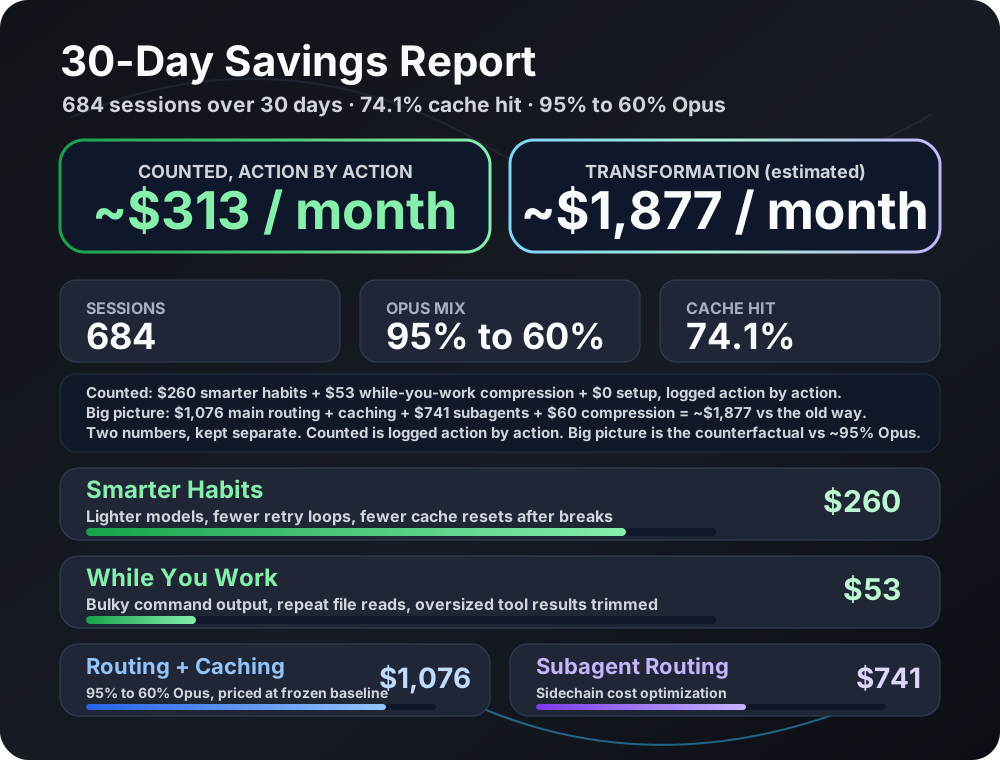
This is a different kind of number from the Terminal-Bench floor and the Controlled A/B. It is not a benchmark. It is the author’s own savings ledger over the last 30 days of everyday work, with all six levers running. It shows the shape of the saving when everything fires. It does not predict yours.
Every figure on this page is the same 30-day window (2026-08-15 to 2026-09-14, snapshot taken 2026-09-14) from the same local ledger, and your dashboard computes the identical report from your own sessions.
≈ $1,396
API-equivalent value, 30 days. Three tiers, labelled by how each is known: $126 logged action by action, $1,124 of repeat reads avoided, $146 of other estimates.
59.6M tokens
Never sent to the model. About 28% of the month’s workload prevented: the month cost 150.8M tokens, and the same work without Token Optimizer would have cost about 210.4M.
| Tier | Value | How it is known |
|---|---|---|
| Logged actions | $126 | Metered. Each saving logged as it happened: a result archived, a repeat read skipped, a lean resume, a loop cut short. 2,733 events. |
| Repeat reads avoided | $1,124 | Estimated. Content Token Optimizer removed would have been re-read on every later turn until the session’s next real compaction. 2,153 removals, modelled per turn at that turn’s cache-read rate, capped at the real compaction event. |
| Other estimates | $146 | Estimated. Lean session resumes, compressed sub-agent context, MCP output caps, loops prevented, hint-served reads. Each listed below. |
| Total | $1,396 | Tokens are the primary figure; dollars depend on which models you run and are shown second for that reason. |
Metered means each saving was logged as it happened. Estimated means the saving is modelled from what happened. Estimates are always shown separately and never dressed up as metered.
| Tokens | Share | |
|---|---|---|
| Spent (fresh input plus de-duplicated output) | 150.8M | 71.7% |
| Saved, metered | 25.4M | 12.1% |
| Saved, estimated | 34.2M | 16.2% |
| Would have been sent without Token Optimizer | 210.4M |
| Measure | Value |
|---|---|
| Sessions | 1,698 main sessions, plus 104 sub-agent sidechains |
| Platform | Claude Code CLI (the author’s primary platform) |
| Average prompt-cache hit rate | 67.2% |
| Quality-scored sessions, all-time | 5,210 (ledger begins 2026-05-30) |
The directly-metered tier: output Token Optimizer shrank, evicted, or never let through, logged with before and after token counts as the sessions actually ran. Dollars are repriced to each session’s own model mix.
| Mechanism | Events | Tokens removed | Saved |
|---|---|---|---|
| Tool-output archive | 1,113 | 18.80M | $100.09 |
| Archive re-fetch blocked | 103 | 2.38M | $12.71 |
| Lean-output nudge (measured) | 291 | 1.21M | $6.42 |
| Bash output compression (pipelines, git, generic) | 883 | 2.73M | $5.83 |
| Loop detection | 124 | 0.12M | $0.35 |
| Checkpoint restores | 113 | 0.08M | $0.34 |
| Cross-turn dedup | 23 | 0.11M | $0.21 |
| Structure maps (re-reads) | 4 | 9.5K | $0.05 |
| Delta reads | 5 | −0.5K | −$0.00 |
| Quality nudges | 74 | 0 | $0.00 |
| Total | 2,733 | 25.43M | $126.00 |
Delta reads ran at a small net loss this month: five events where the diff was longer than the file. It is reported as measured, not hidden.
Lean-output nudge. When context fills past 25%, a short cache-safe note (injected as
additionalContext, never rewriting the existing prefix) tells the model to reason deeply but keep
its visible output lean. Each nudge records the session’s pre-nudge average output tokens, then
meters the actual post-nudge output against it: max(0, pre-nudge average − post-nudge average) × post-nudge turns. Never an estimate, never negative, and never booked until post-nudge turns exist.
Behavioral savers. Quality nudges and loop detection prevent waste instead of removing it. Both log an event when they fire and are low-volume by design; their payoff is avoided degradation and avoided retry loops, not a headline dollar figure.
| Measure | 30 days |
|---|---|
| Removals counted | 2,153 |
| Tokens removed at the time | 20.5M |
| Re-read tokens avoided on later turns | 1.99B |
| Value at each turn’s cache-read rate | $1,124.13 |
Only metered-magnitude removals count here. Every removal is multiplied by the de-duplicated number of turns until that session’s next real compaction event, priced at the per-turn cache-read rate, and stops at the compaction. Lean resumes and other estimated-magnitude events are excluded so nothing is counted twice.
| Source | Volume | Tokens | Saved |
|---|---|---|---|
| Lean session resumes (cold reload avoided) | 156 resumes | 31.85M | $105.16 |
| Sub-agent runtime compression | 846 dispatches | 5.60M | $27.99 |
| MCP output cap | 466 capped results | 2.33M | $11.72 |
| Loops prevented (continuations not run) | 131 events | 0.13M | $0.67 |
| Hint-served reads | 2 hints used | 10K | $0.05 |
| Total | $145.60 |
The 7-signal quality score rolls up to an S/A/B/C/D/F grade. Across the 1,698 main sessions in this window:
| Grade | Sessions | Reading |
|---|---|---|
| S | 714 | Exceptional: minimal waste, high decision density |
| A | 210 | Good: clean context, efficient tool use |
| B | 463 | Normal: some bloat, recoverable |
| C | 77 | Degraded: significant waste, coaching recommended |
| D | 162 | Poor: heavy bloat, likely retries or loops |
| F | 72 | Failing: near-total waste |
The grade scale is identical on every platform, so grades compare across hosts even when the underlying signal count differs (3 to 7 signals).
Large code files on first read that are unlikely to be edited soon can be served as a skeleton,
with the full original archived and retrievable via expand, a ranged Read, or a direct Edit. A
cohort (language plus size band) is only promoted to active serving after proof from real history:
the edit-within-5-turns rate must stay under 15% across 20 or more reads in 5 or more distinct
sessions.
A live tripwire watches every active cohort. If a cohort’s live edit-after-skeleton rate ever
crosses 15%, it auto-demotes to measure-only and logs a cohort_demoted event. Demotions are
sticky to prevent flapping; re-promotion is explicit (measure.py cohorts promote <lang:band>) or
happens on the next history backfill. The full original is always archived before any skeleton is
served, and if archiving fails the full file is served unchanged (fail-open).
As of this snapshot the tripwire has demoted all four code cohorts: live edit-after-skeleton rates
of 16.0% (Python 16-64KB), 16.7% (Python 64-256KB), 50.0% (TypeScript 16-64KB) and 40.0%
(TypeScript 64-256KB), each above the 15% gate. The history backfill still rates the same cohorts
promotion-ready on their all-time edit rate (0.6% to 1.5%), which is exactly the disagreement the
tripwire exists to catch: live behaviour wins. Markdown cohorts stay measure-only by policy, because
a headings-only outline drops load-bearing prose. The first-read retarget that shipped in v2
serves the file you opened in full and moves the compression budget to skeletons of the related
files around it; see Read cache. Both flags are visible and toggleable in
measure.py v5 status.
The benchmark harness writes its own test-fixture events into the same local ledger. In this window
that was 766 events (7.2M tokens, $14.47) tagged f3bench-session-0001 and test-session-*,
recorded between 2026-08-31 and 2026-09-06. They are excluded from every figure on this page.
# The savings ledger behind the tiers above (last 30 days)python3 scripts/measure.py savingspython3 scripts/measure.py savings --json
# Live compression events from your history databasepython3 scripts/measure.py compression-stats --days 30 --json
# Cohort status and tripwire statepython3 scripts/measure.py cohorts status --json
# Full dashboard (the same report, visualized)python3 scripts/measure.py dashboard
Your number is your own. Savings scale with how much read-heavy, multi-file work you do. Someone who mostly chats will see less. Someone who lives in large codebases with long sessions will see more. Token Optimizer computes this same report from your own history, so you never have to take this month’s figure on trust.